Navier–Stokes (2D)
Auto-generated 2026-10-17 09:01 UTC · 13 plots
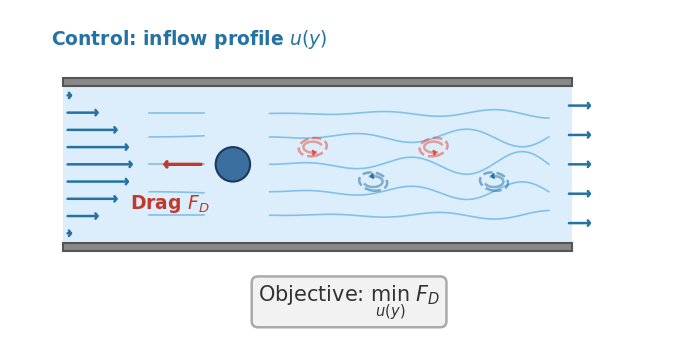
Optimize the inflow of a 2D channel flow to minimize drag on a cylinder, differentiating through an incompressible fluid solver.
Fluid flow in 2D. We simulate an incompressible fluid (think of stirred water) and differentiate through the simulation. The headline question is whether each solver returns a trustworthy gradient as the flow becomes chaotic.
Formally, we solve the 2D incompressible Navier–Stokes equations \(\partial_t \mathbf{u} + (\mathbf{u}\cdot\nabla)\mathbf{u} = -\nabla p + \nu\,\nabla^2\mathbf{u}\), \(\nabla\cdot\mathbf{u}=0\), with the kinematic viscosity \(\nu\) as the primary control parameter. The nonlinear advection term \(\nabla\cdot(\mathbf{u}\otimes\mathbf{u})\) transfers energy across scales; at low \(\nu\) the flow develops turbulent cascades and a positive Lyapunov exponent, so long-horizon gradients grow exponentially sensitive to perturbations. This is the regime where backprop-through-simulation is hardest.
These are example results, produced automatically on GitHub Actions runners and refreshed on every release. Each solver runs on its intended device: GPU-capable solvers on a Tesla T4 GPU node, CPU-only solvers (OpenFOAM, INS.jl, deal.II, FEniCS, Firedrake, TopOpt.jl) on a separate CPU node, whose processor model can differ between runs. Accuracy and gradient metrics are hardware-independent and reproducible. Wall-clock numbers reflect commodity cloud hardware and can vary by 10–15% between runs, so read them for relative scaling between solvers rather than as absolute timings. For numbers that reflect your setup, run the benchmarks yourself on your target hardware.
Doubly-periodic square domain \([0, 2\pi]^2\) (the flow wraps around at every edge), with incompressibility \(\nabla\cdot\mathbf{u}=0\) enforced by a pressure projection at each time step. The cylinder experiments use the Schäfer–Turek DFG 2D-1 channel instead: \([0, 2.2] \times [0, 0.41]\) with a cylinder of diameter 0.1 at \((0.2, 0.2)\), a parabolic inflow of mean speed 0.2 on the left, a zero-gradient outflow at \(p=0\) on the right, and no-slip walls; \(\nu = 10^{-3}\), so \(Re = 20\).
Initial Conditions
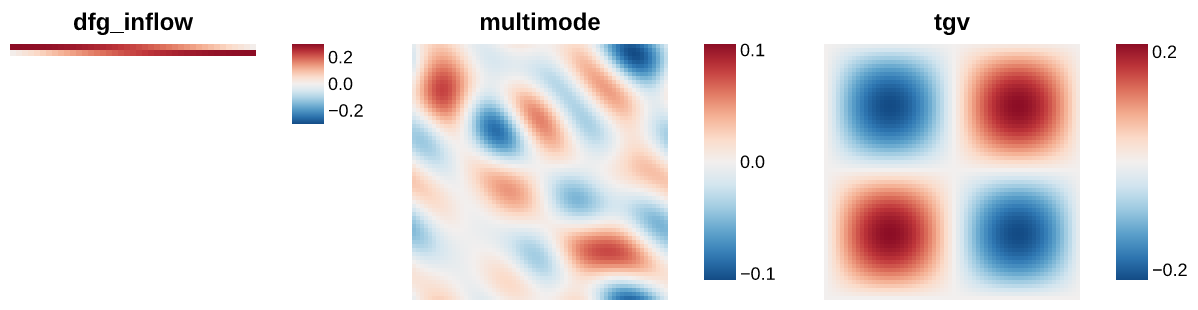
Visualisation of each initial condition (the starting field a run is launched from) available for this problem. IC plots are generated without running any solver.
Dfg Inflow
{
  "resolution": 20
}
Flat Inflow
{
  "N": 64,
  "U": 0.5
}
Multimode
{
  "N": 64
}
Tgv
{
  "N": 64
}
Uniform
{
  "N": 64,
  "U": 1.0
}
Forward
Is the prediction right? Forward-pass benchmarks check each solver’s output against a trusted reference (and an analytic solution where one exists): inter-solver agreement, field-level diagnostics, and long-run stability.
Baseline
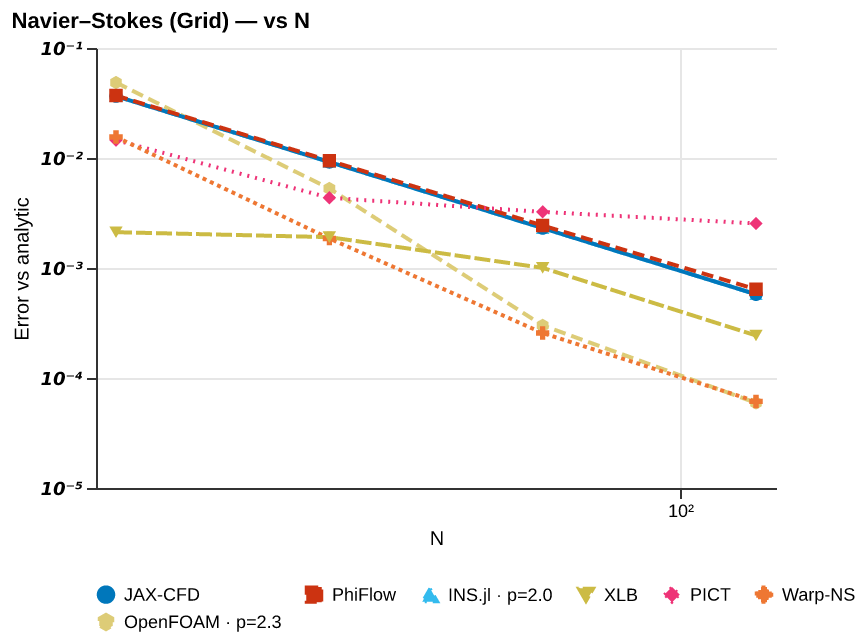
Relative error vs grid resolution \(N\) against the analytic TGV solution at \(t=1.28\), refining space and time together at a fixed CFL number. The legend gives each solver’s observed order of accuracy \(p\).
Sweeps N ∈ {16, 32, 64, 128}
{
  "ic": {
    "name": "tgv",
    "seed": 0
  },
  "physics": {
    "N": 16,
    "nu": 0.05,
    "dt": 0.01,
    "steps": 128,
    "cfl_N_base": 128
  },
  "sweep": {
    "key": "N",
    "values": [
      16,
      32,
      64,
      128
    ]
  }
}
Cylinder
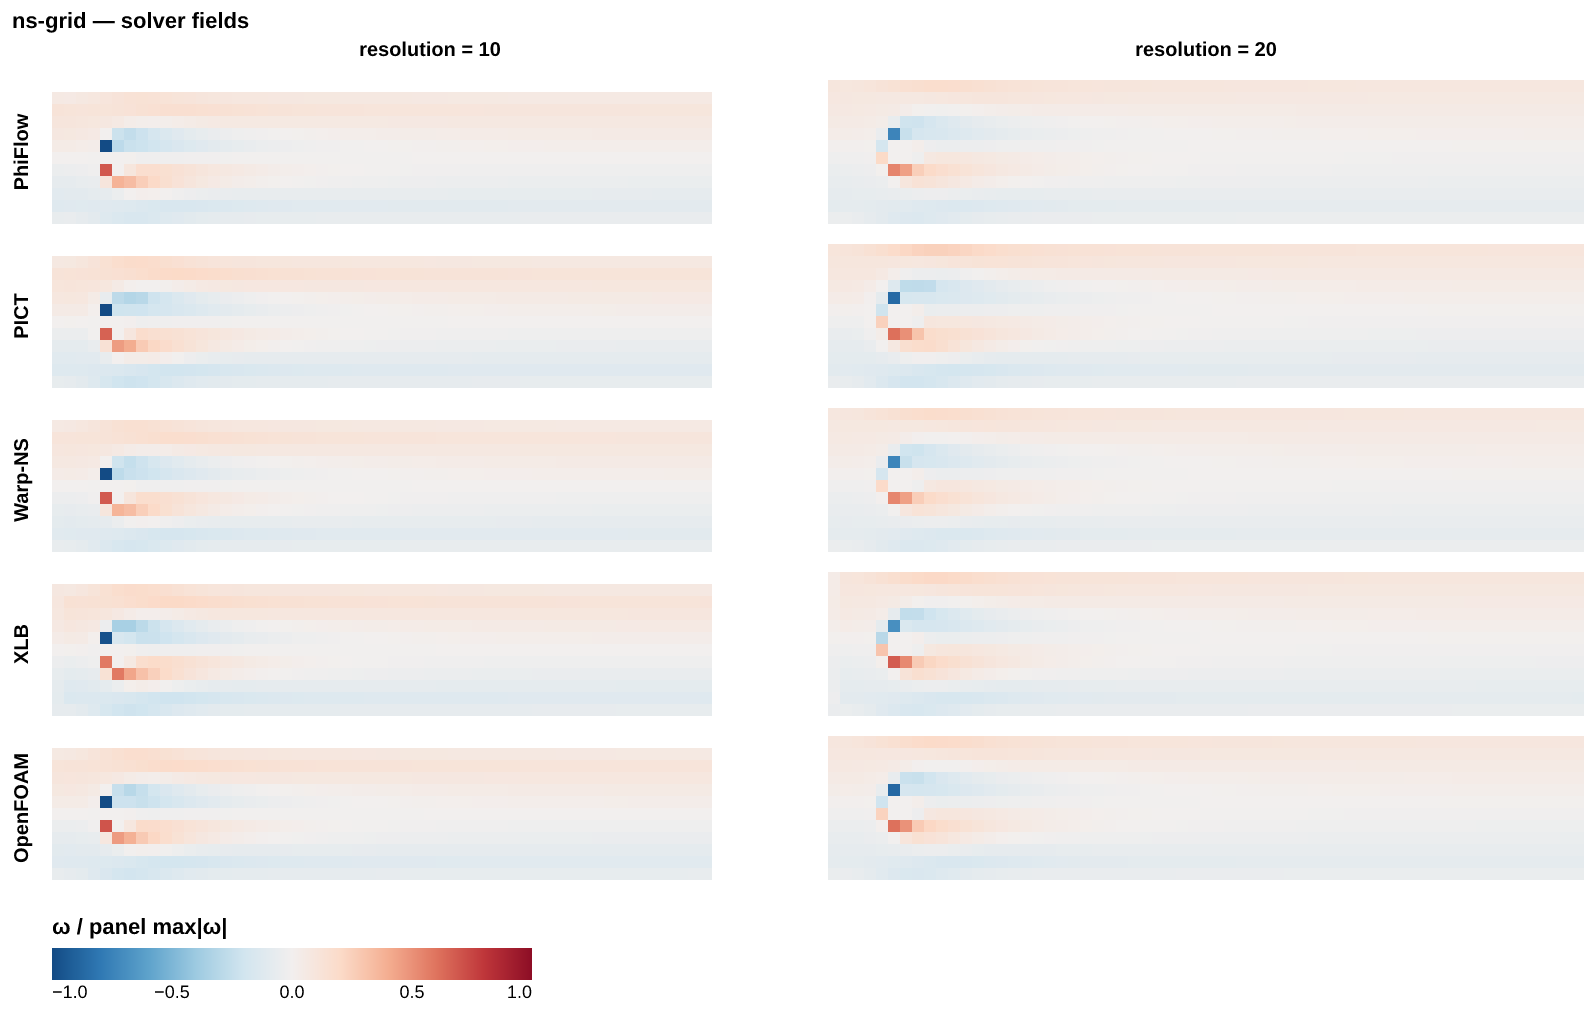
Steady flow past a cylinder in a channel (Schäfer–Turek DFG 2D-1, Re = 20) at 10 and 20 cells per diameter. Each solver’s drag coefficient at 20 is scored against the reference Cd = 5.5795. The pressure difference across the cylinder (reference 0.1175) and the lift coefficient are also reported. The vorticity fields are for visual comparison.
Sweeps resolution ∈ {10, 20}
{
  "ic": {
    "name": "dfg_inflow",
    "seed": 0
  },
  "physics": {
    "resolution": 10
  },
  "sweep": {
    "key": "resolution",
    "values": [
      10,
      20
    ]
  }
}
Tgv Nu Sweep
Relative error vs viscosity \(\nu\) for each solver at a fixed TGV initial condition.
Sweeps nu ∈ {0.0001, 0.0005, 0.001, 0.005, 0.01, 0.05}
{
  "ic": {
    "name": "tgv",
    "seed": 42
  },
  "physics": {
    "N": 64,
    "dt": 0.05,
    "steps": 20,
    "nu": 0.0001
  },
  "sweep": {
    "key": "nu",
    "values": [
      0.0001,
      0.0005,
      0.001,
      0.005,
      0.01,
      0.05
    ]
  }
}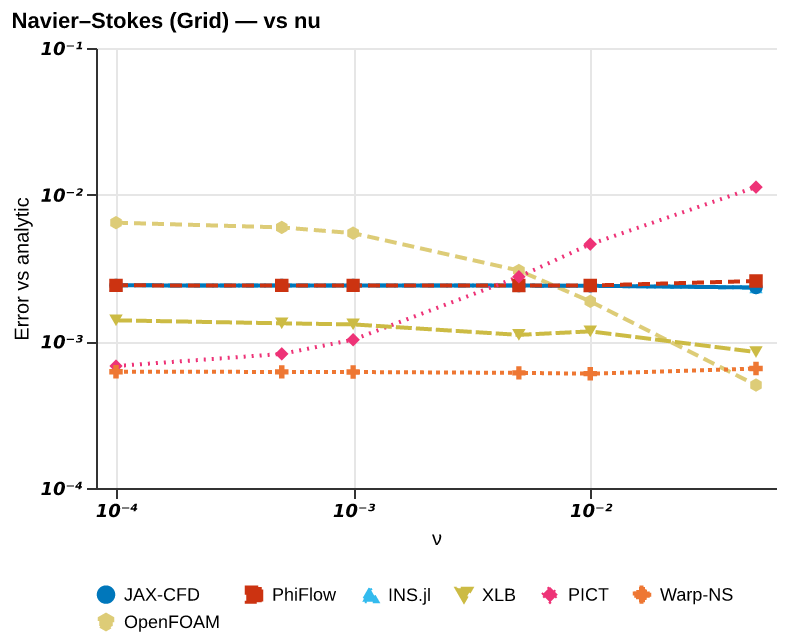
Solver ranking
| Solver | Mean rel. error |
|---|---|
| Warp-NS | 6.20e-04 |
| XLB | 1.19e-03 |
| jax-cfd | 2.39e-03 |
| INS.jl | 2.39e-03 |
| PhiFlow | 2.43e-03 |
| PICT | 3.52e-03 |
| OpenFOAM | 3.88e-03 |
Ranked by mean relative error against the reference solution (lower is more accurate).
Cost
What does it cost? Wall-clock scaling of the forward and VJP passes with problem size \(N\) and the number of integration steps. Timings come from dedicated runners with no concurrent workloads; see the reliability note at the top of the page before reading absolute numbers.
Spatial Cost
Sweeps N ∈ {64, 128, 192, 256}
{
  "physics": {
    "nu": 0.01,
    "dt": 0.01,
    "steps": 100,
    "N": 64
  },
  "cost": {
    "n_trials": 3
  },
  "sweep": {
    "key": "N",
    "values": [
      64,
      128,
      192,
      256
    ]
  }
}
Temporal Cost
Sweeps steps ∈ {10, 50, 100, 500, 1000}
{
  "physics": {
    "nu": 0.01,
    "dt": 0.01,
    "N": 128,
    "steps": 10
  },
  "cost": {
    "n_trials": 3
  },
  "sweep": {
    "key": "steps",
    "values": [
      10,
      50,
      100,
      500,
      1000
    ]
  }
}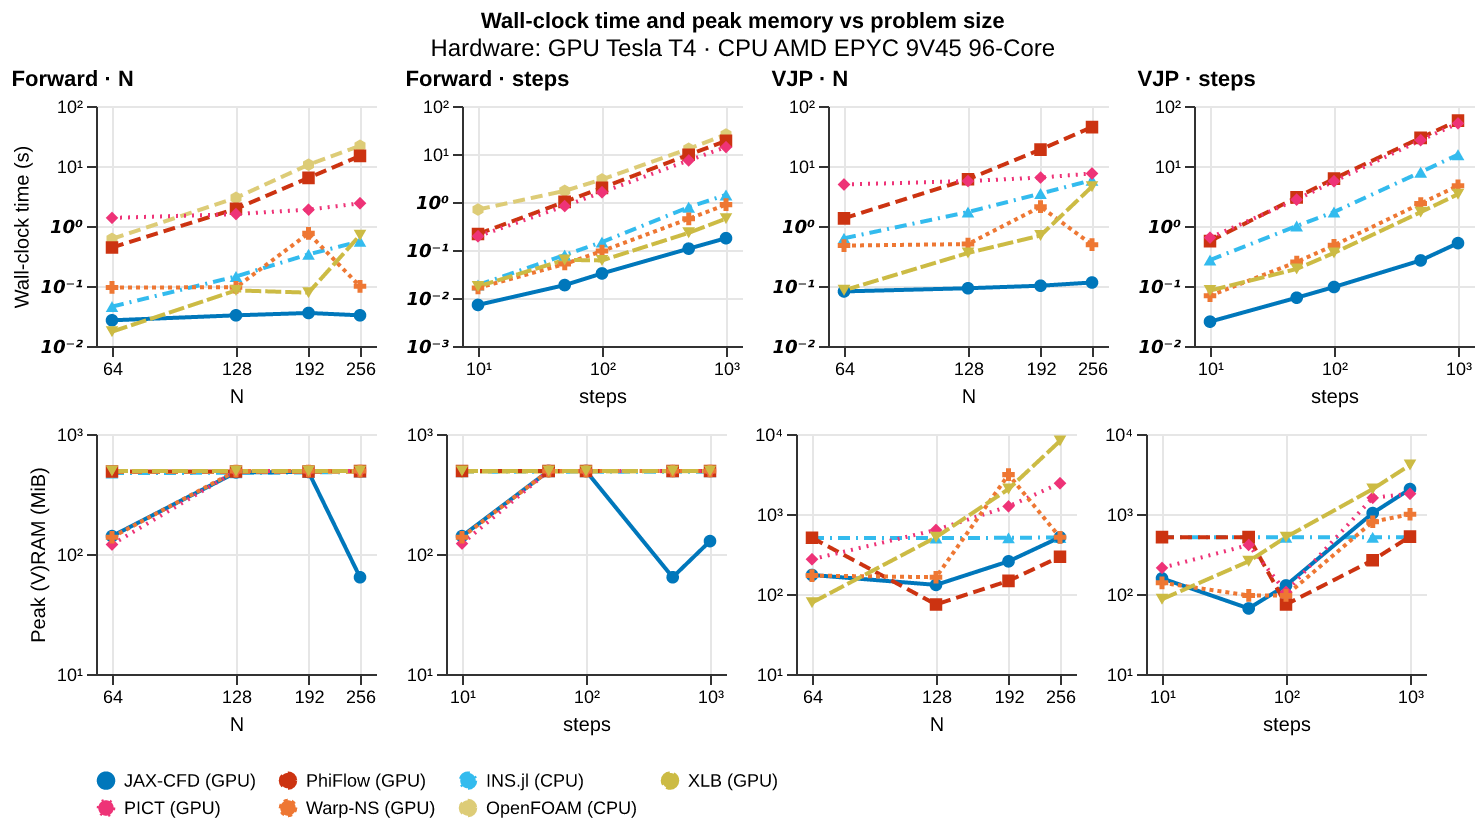
Solver ranking
| Solver | Forward time | VJP time |
|---|---|---|
| jax-cfd | 0.0324 s @ N=256 | 0.114 s @ N=256 |
| Warp-NS | 0.0987 s @ N=256 | 0.489 s @ N=256 |
| INS.jl | 0.554 s @ N=256 | 5.8 s @ N=256 |
| XLB | 0.701 s @ N=256 | 4.53 s @ N=256 |
| PICT | 2.39 s @ N=256 | 7.5 s @ N=256 |
| PhiFlow | 14.7 s @ N=256 | 44.6 s @ N=256 |
| OpenFOAM | 21.7 s @ N=256 | — |
Forward and VJP wall-clock time, each shown at the largest problem size N the solver completed for that pass; ranked by forward time (faster is better). The VJP time is one gradient from scratch, a forward plus an adjoint pass. Forward-only solvers have no VJP entry. See the reliability note above before comparing across devices.
Gradient
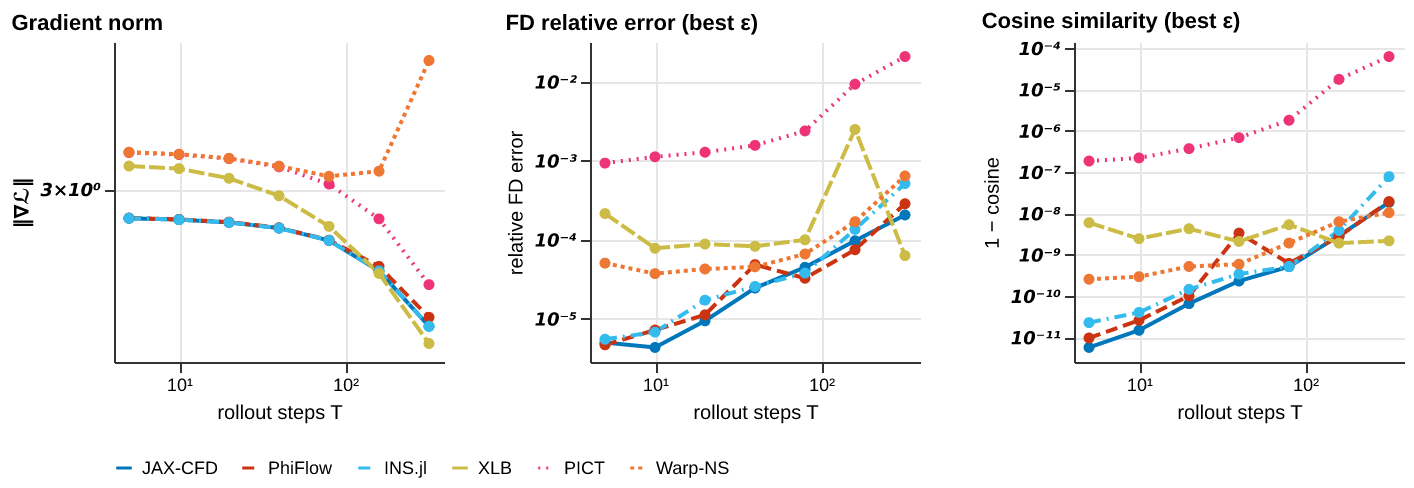
Is the gradient right? Gradient benchmarks compare each solver’s AD/adjoint gradient against a finite-difference ground truth. We report magnitude error (relative \(L^2\)) and direction agreement (cosine similarity) across parameter, resolution, and horizon sweeps. The horizon sweep in particular exposes how gradients degrade as the rollout lengthens.
Fd Check
{
  "ic": {
    "name": "multimode",
    "seed": 42
  },
  "physics": {
    "N": 16,
    "nu": 0.001,
    "dt": 0.05,
    "steps": 20
  },
  "fd": {
    "eps_values": [
      5.0,
      1.0,
      0.1,
      0.01,
      0.001,
      0.0001
    ],
    "n_dirs": 20
  }
}
Horizon Sweep
Sweeps steps ∈ {5, 10, 20, 40, 80, 160, 320}
{
  "ic": {
    "name": "multimode",
    "seed": 42
  },
  "physics": {
    "N": 16,
    "nu": 0.001,
    "dt": 0.05,
    "steps": 5
  },
  "fd": {
    "eps_values": [
      1.0,
      0.1,
      0.01,
      0.001
    ],
    "n_dirs": 8
  },
  "sweep": {
    "key": "steps",
    "values": [
      5,
      10,
      20,
      40,
      80,
      160,
      320
    ]
  }
}
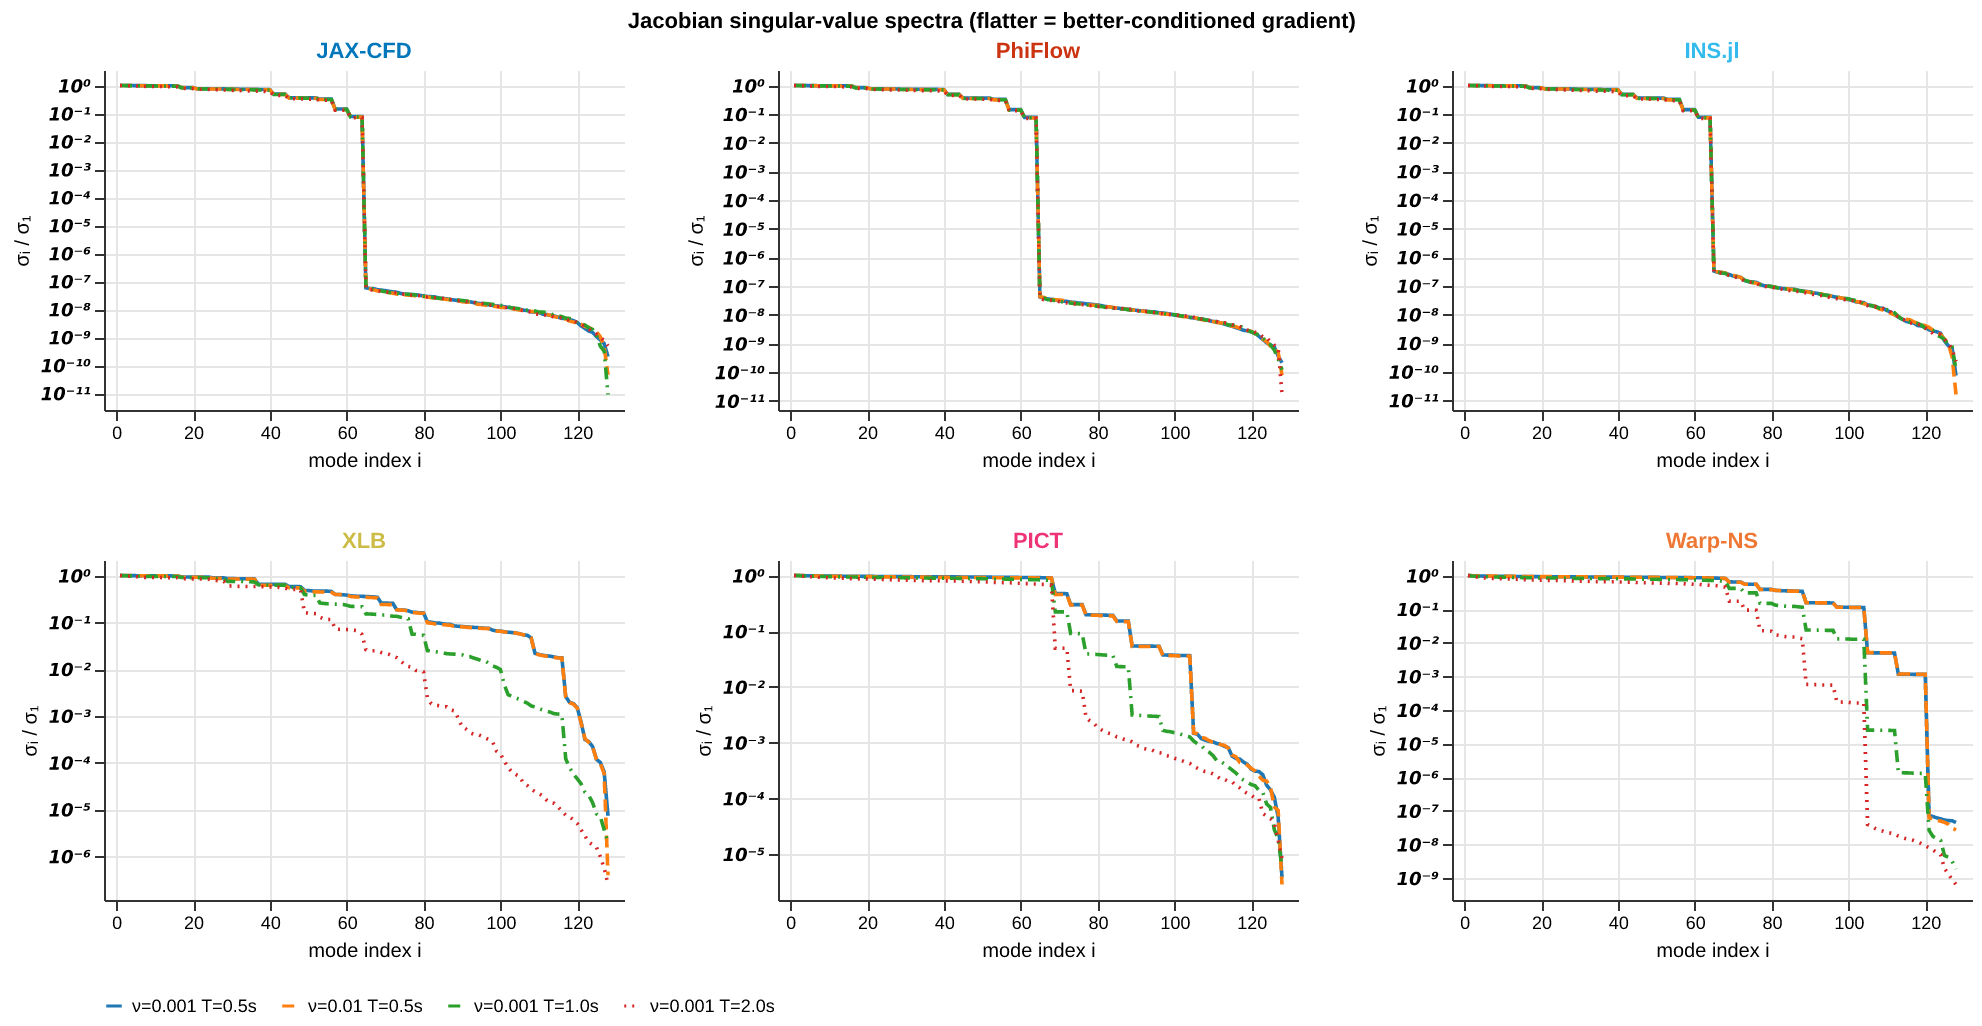
Jacobian Svd
{
  "ic": {
    "name": "multimode",
    "seed": 42
  },
  "physics": {
    "N": 8,
    "nu": 0.001,
    "dt": 0.05,
    "steps": 10
  }
}
Jacobian Svd Nu01
{
  "ic": {
    "name": "multimode",
    "seed": 42
  },
  "physics": {
    "N": 8,
    "nu": 0.01,
    "dt": 0.05,
    "steps": 10
  }
}
Jacobian Svd Steps20
{
  "ic": {
    "name": "multimode",
    "seed": 42
  },
  "physics": {
    "N": 8,
    "nu": 0.001,
    "dt": 0.05,
    "steps": 20
  }
}
Jacobian Svd Steps40
{
  "ic": {
    "name": "multimode",
    "seed": 42
  },
  "physics": {
    "N": 8,
    "nu": 0.001,
    "dt": 0.05,
    "steps": 40
  }
}
Param Sweep
Sweeps nu ∈ {0.05, 0.01, 0.005, 0.001}
{
  "ic": {
    "name": "multimode",
    "seed": 42
  },
  "physics": {
    "N": 16,
    "dt": 0.05,
    "steps": 200,
    "nu": 0.05
  },
  "fd": {
    "eps_values": [
      5.0,
      1.0,
      0.1,
      0.01,
      0.001
    ],
    "n_dirs": 15
  },
  "sweep": {
    "key": "nu",
    "values": [
      0.05,
      0.01,
      0.005,
      0.001
    ]
  }
}
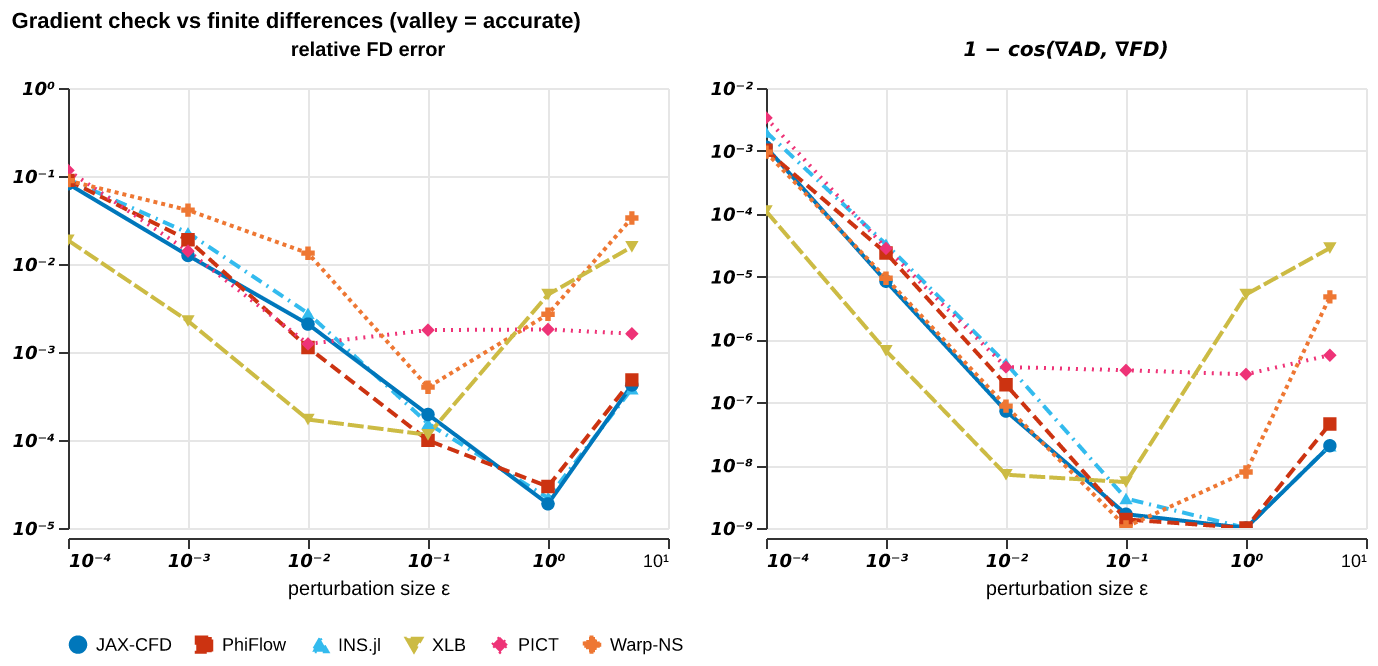
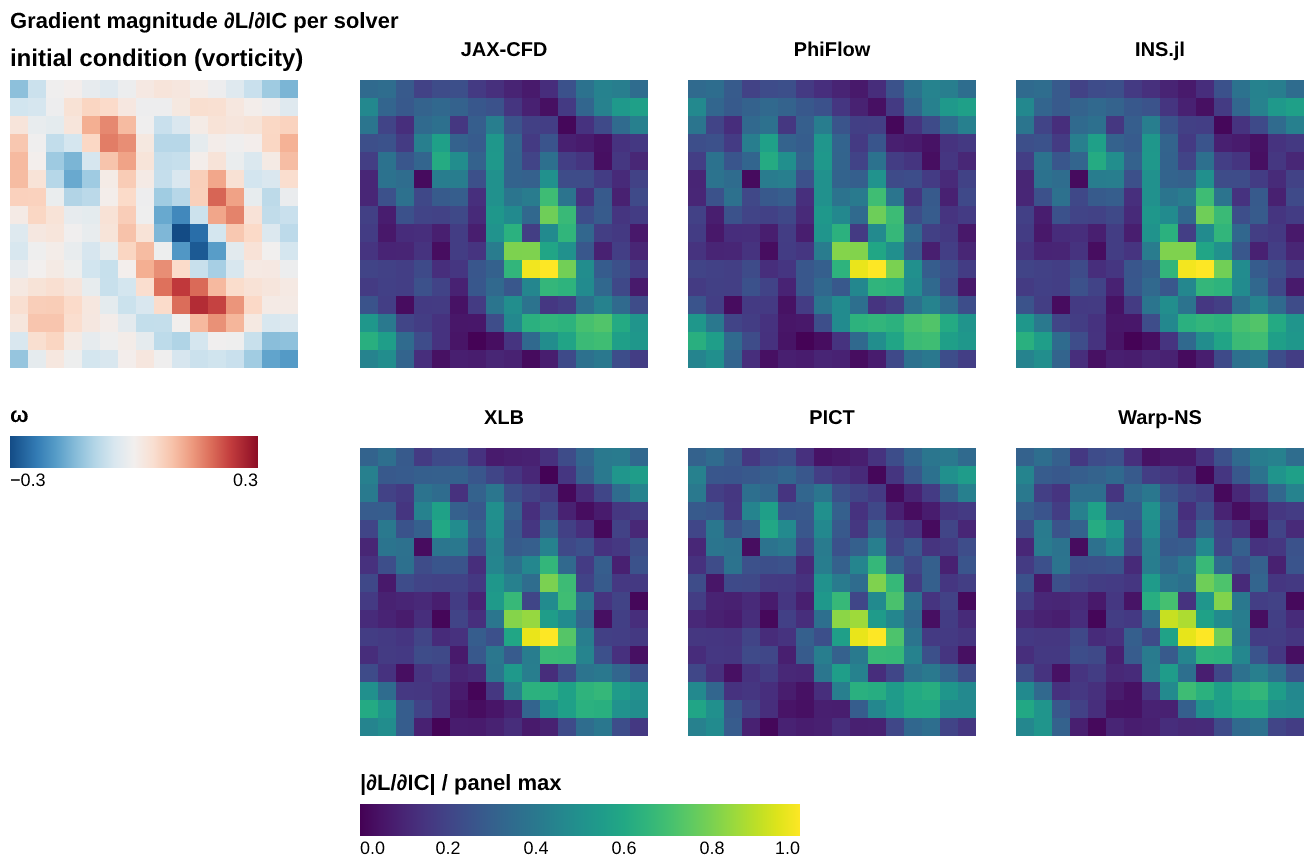
Finite-Difference Check
U-curves of finite-difference gradient error vs perturbation size \(\varepsilon\) together with subspace cosine; validates VJP correctness.
{
  "ic": {
    "name": "multimode",
    "seed": 42
  },
  "physics": {
    "N": 16,
    "nu": 0.001,
    "dt": 0.05,
    "steps": 20
  },
  "fd": {
    "eps_values": [
      5.0,
      1.0,
      0.1,
      0.01,
      0.001,
      0.0001
    ],
    "n_dirs": 20
  }
}
Parameter Sweep
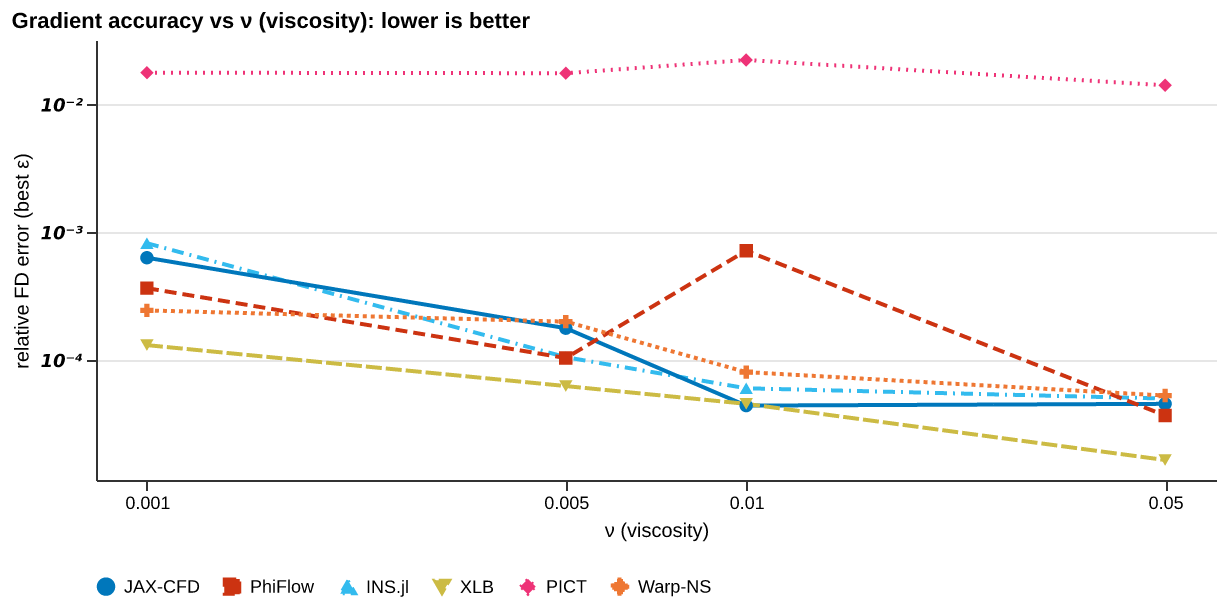
Gradient norm, best-\(\varepsilon\) FD error, direction cosine, and U-curves vs the sweep parameter.
Sweeps nu ∈ {0.05, 0.01, 0.005, 0.001}
{
  "ic": {
    "name": "multimode",
    "seed": 42
  },
  "physics": {
    "N": 16,
    "dt": 0.05,
    "steps": 200,
    "nu": 0.05
  },
  "fd": {
    "eps_values": [
      5.0,
      1.0,
      0.1,
      0.01,
      0.001
    ],
    "n_dirs": 15
  },
  "sweep": {
    "key": "nu",
    "values": [
      0.05,
      0.01,
      0.005,
      0.001
    ]
  }
}
Horizon Sweep
Gradient norm, FD error, and direction cosine vs rollout horizon \(T = \mathrm{steps}\cdot dt\).
Sweeps steps ∈ {5, 10, 20, 40, 80, 160, 320}
{
  "ic": {
    "name": "multimode",
    "seed": 42
  },
  "physics": {
    "N": 16,
    "nu": 0.001,
    "dt": 0.05,
    "steps": 5
  },
  "fd": {
    "eps_values": [
      1.0,
      0.1,
      0.01,
      0.001
    ],
    "n_dirs": 8
  },
  "sweep": {
    "key": "steps",
    "values": [
      5,
      10,
      20,
      40,
      80,
      160,
      320
    ]
  }
}
Solver ranking
| Solver | Best-ε FD error | 1 − cosine |
|---|---|---|
| jax-cfd | 8.33e-06 | 4.90e-11 |
| PhiFlow | 1.07e-05 | 1.08e-10 |
| INS.jl | 1.29e-05 | 9.26e-11 |
| Warp-NS | 3.43e-05 | 1.04e-09 |
| XLB | 9.19e-05 | 5.37e-09 |
| PICT | 8.84e-04 | 5.62e-07 |
Ranked by the best-ε finite-difference error of the gradient (lower is more trustworthy); direction cosine near 1 confirms the gradient points the right way.
Optimization
Can you optimize through it? End-to-end optimization benchmarks run a gradient-based optimizer using each solver’s own gradients: recovery of initial conditions or physical parameters, topology optimization, and drag minimization. This is the ultimate test, since a gradient can pass the finite-difference check yet still fail to drive a full optimization loop.
Drag Optimisation
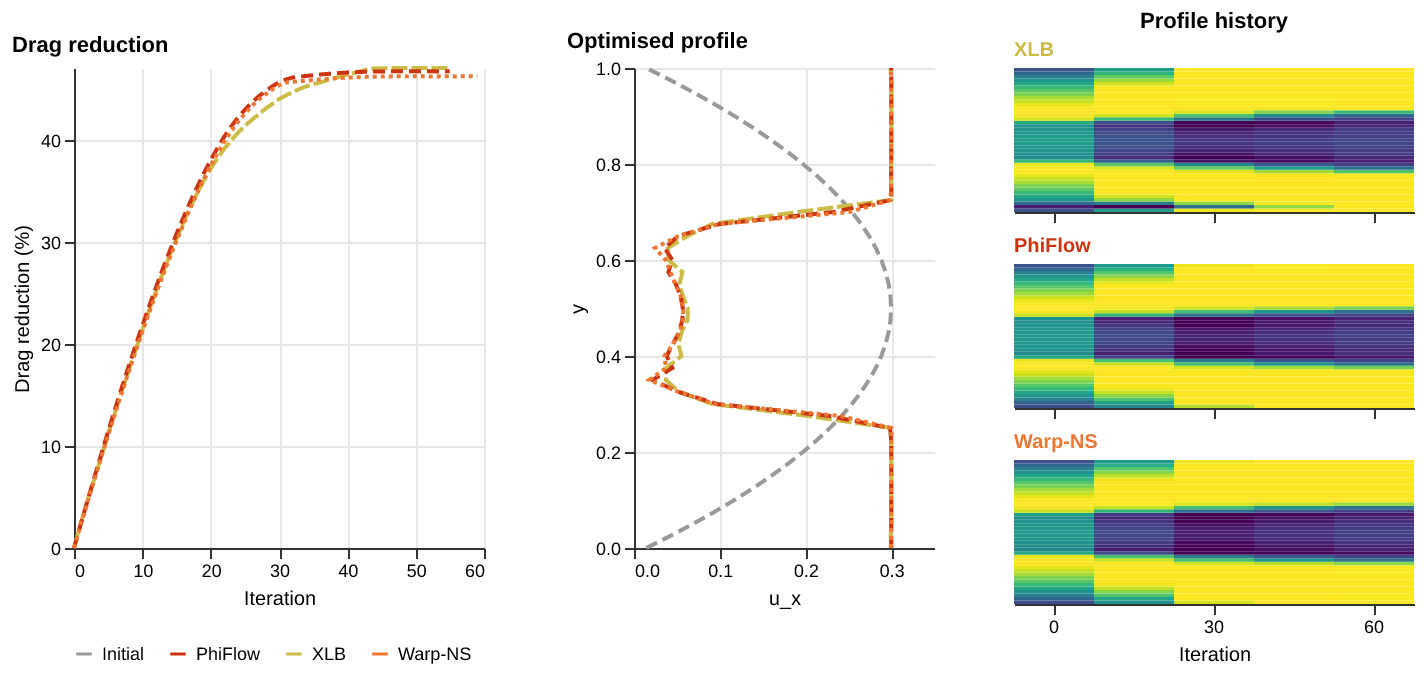
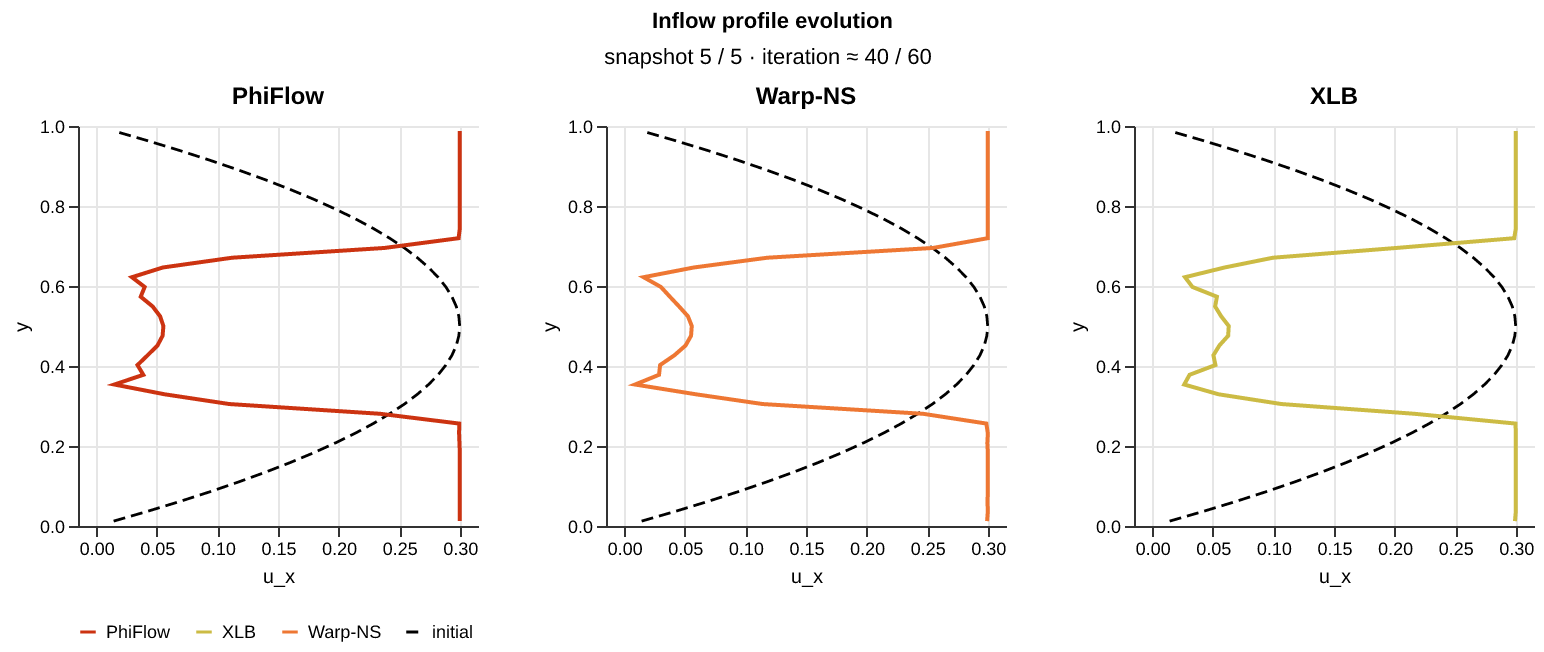
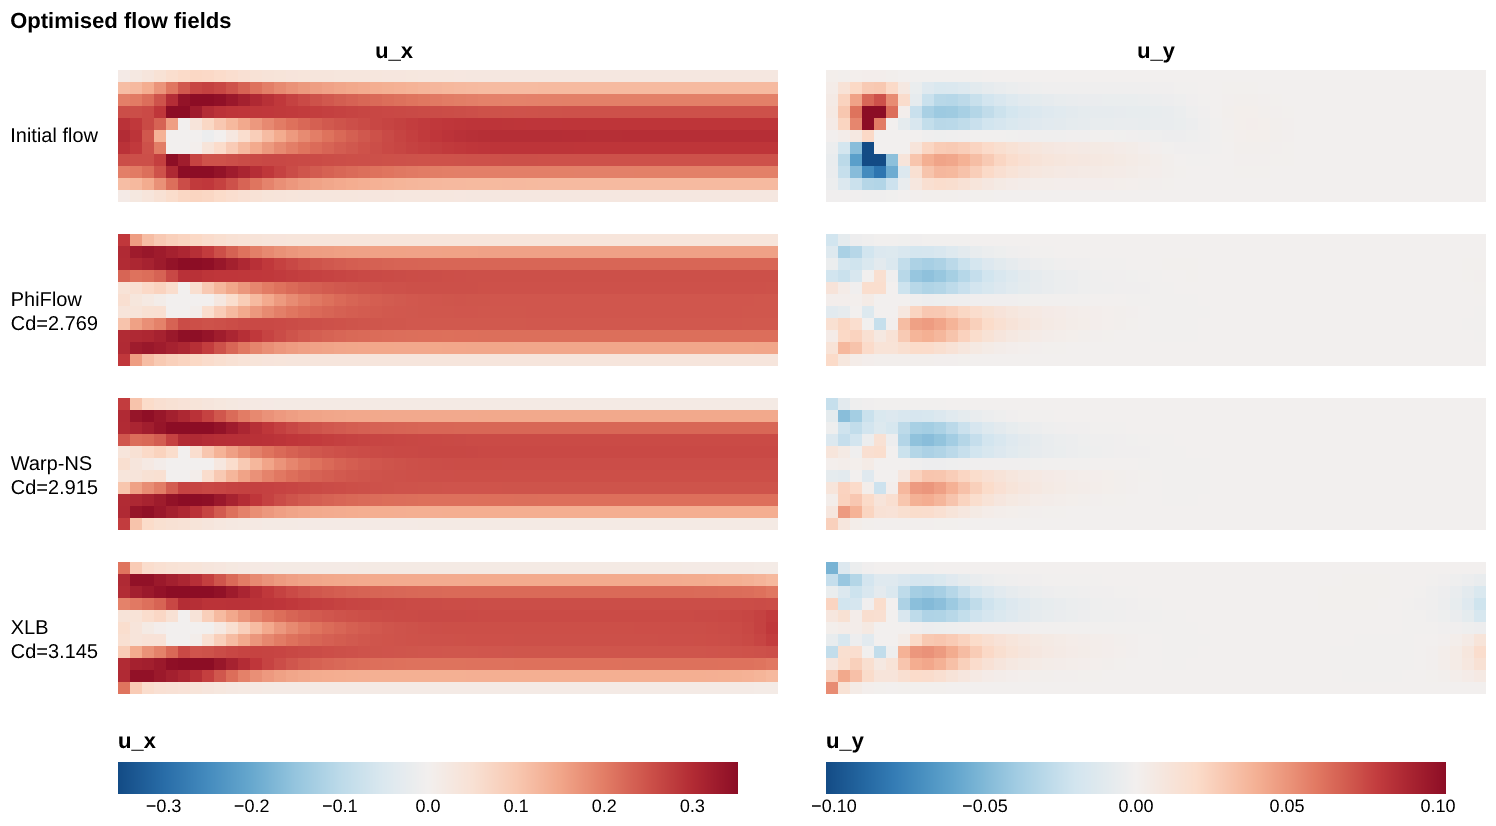
Drag minimization over the inlet profile of the DFG 2D-1 channel at a fixed flow rate: drag coefficient per iteration, optimized vs initial inflow profiles, and the flow fields before and after.
{
  "ic": {
    "name": "dfg_inflow",
    "seed": 0
  },
  "physics": {
    "resolution": 10,
    "t_end": 4.0
  },
  "optim": {
    "lr": 0.01,
    "max_iters": 100,
    "patience": 10,
    "min_rel_improvement": 0.001,
    "snap_interval": 10
  }
}
Solver ranking
| Solver | Final drag | Converged |
|---|---|---|
| PhiFlow | 2.77e+00 | yes |
| Warp-NS | 2.91e+00 | yes |
| XLB | 3.14e+00 | yes |
Ranked by the final objective reached within the iteration budget (lower is better).